Hui Ding

Staff AI Research Scientist, Meta Superintelligence Labs

I build unified multimodal foundation models that bridge understanding, generation, and editing across text, image, video, and audio. I have trained these models at every stage: pretraining, mid-training, and post-training.

At Meta, I work on post-training for Muse Image and Muse Video, and I led mid-training and post-training of the unified generation and editing model behind the Add Me and Remix Me features in Meta AI. Before Meta, I worked on pretraining for Adobe Firefly Image 5 and Amazon Titan Image Generator (Nova Canvas), and on document understanding and facial analysis at AWS AI.

I received my Ph.D. from the University of Maryland, College Park, advised by Prof. Rama Chellappa, and interned at Waymo, Adobe Research, Palo Alto Research Center, and Siemens Healthineers.

Portrait of Hui Ding

Shipped models

Muse Image & Muse Video

Meta Superintelligence Labs · 2026

Meta's image and video generation models. I work across the end-to-end post-training stack: supervised fine-tuning, distillation, reward modeling, and reinforcement learning.

Arena rank at launch

  • #2Text-to-image
  • #2Single-image editing
  • #2Multi-image editing
  • #3Text-to-audio-video

Where my work sits in each model's training pipeline.

Post-training
Add Me & Remix Me Meta AI · Nov 2025 · Led
Mid-training and post-training
Pretraining
Titan Image Generator Amazon · 2023
Pretraining

Experience

  1. Jun 2025 – now

    Meta Superintelligence Labs

    Staff AI Research Scientist

    Post-training for Muse Image and Muse Video. Led mid-training and post-training of a unified model for text-to-image generation, image editing, style transfer, face swap, and person insertion, which powers Add Me and Remix Me in Meta AI.

  2. Jun 2024 – Jun 2025

    Adobe Firefly

    Senior Applied Scientist

    Pretraining for Firefly Image 5, including sparse Mixture-of-Experts and sparse-attention architectures. Led a unified generation and editing framework for image and video, and researched multimodal LLMs for unified understanding and generation.

  3. 2020 – 2024

    Amazon AGI Foundations & AWS AI

    Senior Applied Scientist; previously Applied Scientist

    Pretraining for Titan Image Generator, launched on Amazon Bedrock at AWS re:Invent 2023. Built the core models for Amazon Textract key-value pair detection and document forgery detection, and contributed to Amazon Rekognition face liveness, facial attributes, and face recognition.

  4. Ph.D.

    University of Maryland, College Park

    Electrical and Computer Engineering, advised by Prof. Rama Chellappa

    Research internships at Waymo, Adobe Research, Palo Alto Research Center, and Siemens Healthineers.

Selected publications All papers on Google Scholar

  1. CVPR 2025 · Highlight

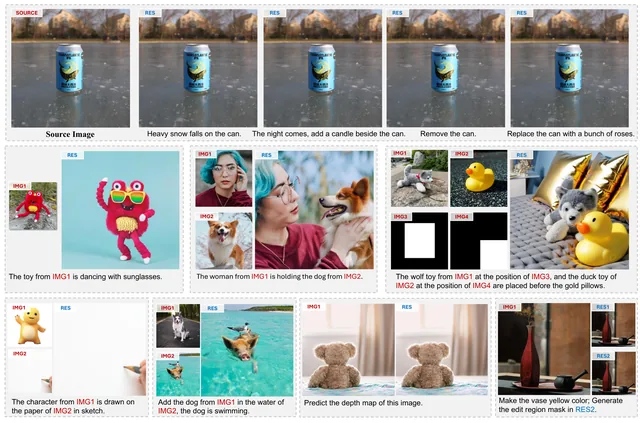
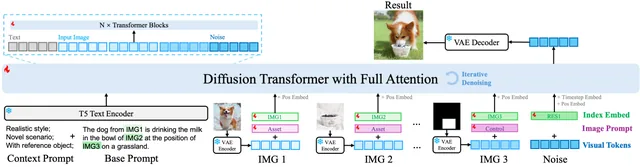
    UniReal: Universal Image Generation and Editing via Learning Real-world Dynamics

    Xi Chen, Zhifei Zhang, He Zhang, Yuqian Zhou, Soo Ye Kim, Qing Liu, Yijun Li, Jianming Zhang, Nanxuan Zhao, Yilin Wang, Hui Ding, Zhe Lin, Hengshuang Zhao

    One model for a broad range of image generation and editing tasks with diverse input and output configurations, producing realistic shadows, reflections, lighting effects, and pose changes.

  2. CVPR 2023

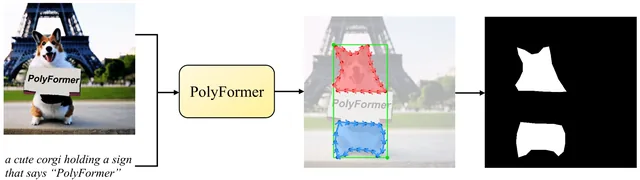
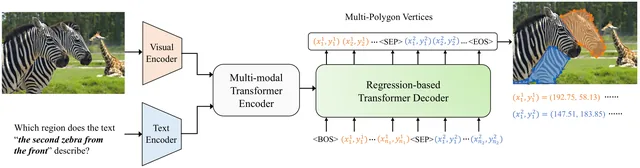
    PolyFormer: Referring Image Segmentation as Sequential Polygon Generation

    Jiang Liu*, Hui Ding*, Zhaowei Cai, Yuting Zhang, Ravi Kumar Satzoda, Vijay Mahadevan, R. Manmatha  (*equal contribution)

    Recasts referring image segmentation as polygon generation: a sequence-to-sequence transformer reads image patches and text tokens and predicts polygon vertices autoregressively.

  3. ICCV 2021 · Oral

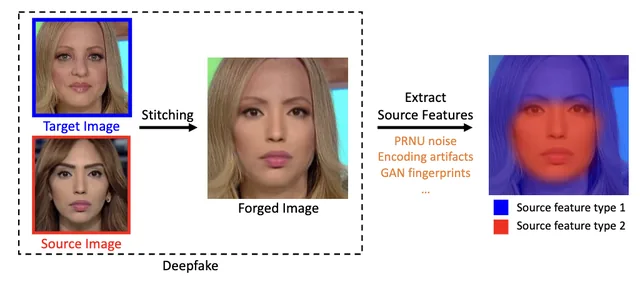
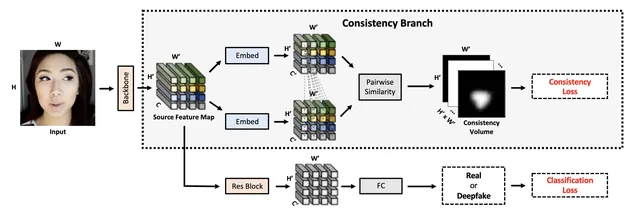
    Learning Self-Consistency for Deepfake Detection

    Tianchen Zhao, Xiang Xu, Mingze Xu, Hui Ding, Yuanjun Xiong, Wei Xia

    Pair-wise self-consistency learning (PCL) trains ConvNets to extract source features that expose deepfake images.

  4. IJCB 2020 · Oral

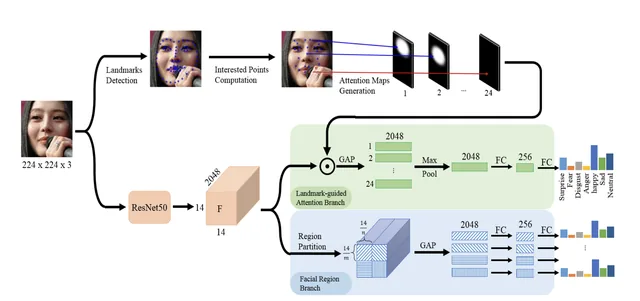
    Occlusion-Adaptive Deep Network for Robust Facial Expression Recognition

    Hui Ding, Peng Zhou, Rama Chellappa

    A landmark-guided attention branch discards features from occluded regions, and a facial-region branch predicts the expression from each facial block independently.

  5. AAAI 2018 · Oral

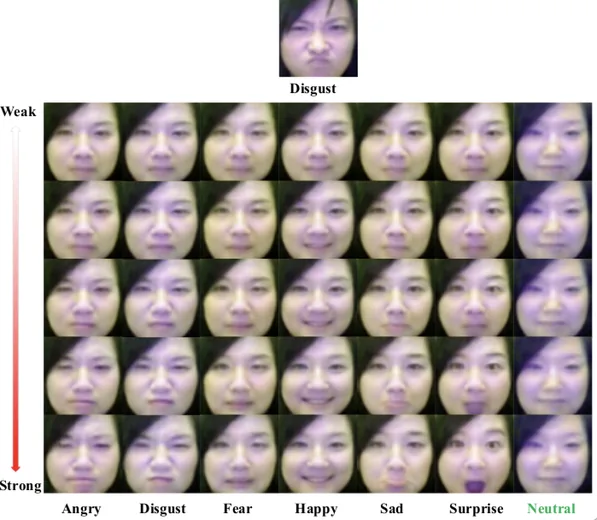
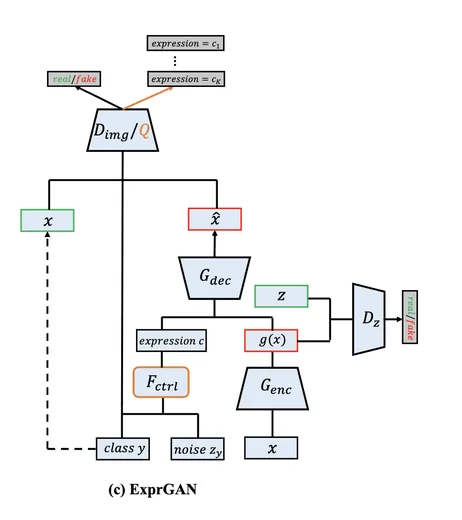
    ExprGAN: Facial Expression Editing with Controllable Expression Intensity

    Hui Ding, Kumar Sricharan, Rama Chellappa

    Photo-realistic facial expression editing, with an expression controller that adjusts intensity continuously from low to high.

  6. AAAI 2018 · Spotlight

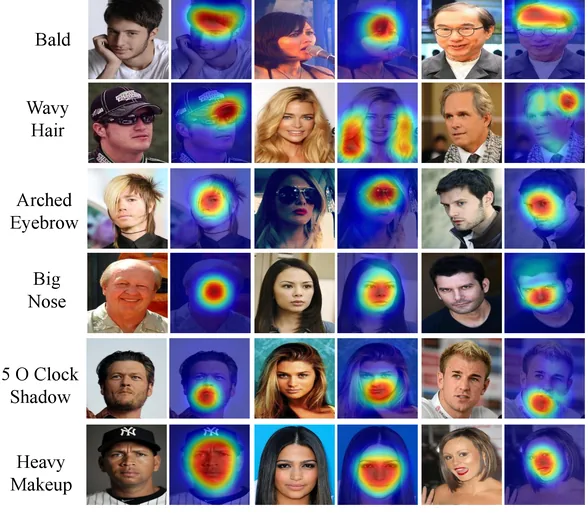
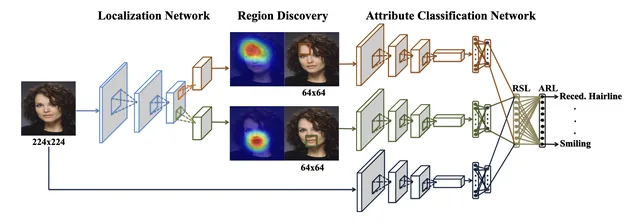
    A Deep Cascade Network for Unaligned Face Attribute Classification

    Hui Ding, Hao Zhou, Shaohua Kevin Zhou, Rama Chellappa

    Localizes attribute-specific face regions with weak supervision and classifies attributes without face alignment.

  7. FG 2017

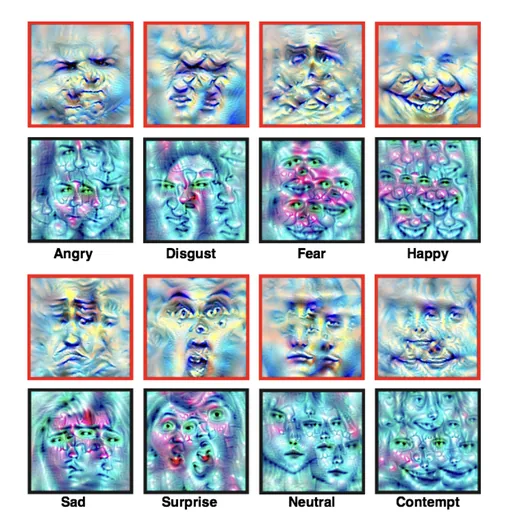
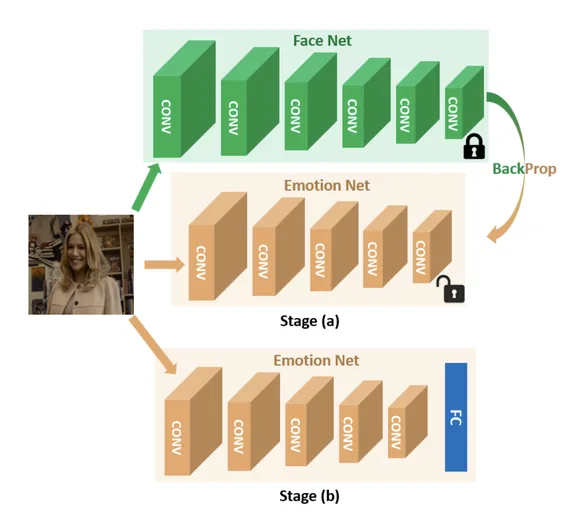
    FaceNet2ExpNet: Regularizing a Deep Face Recognition Net for Expression Recognition

    Hui Ding, Shaohua Kevin Zhou, Rama Chellappa

    A two-stage training algorithm that uses a face recognition network to regularize expression recognition trained on small datasets.

Patents

Service

Reviewer for CVPR, ICCV, ECCV, NeurIPS, ICLR, ICML, IJCV, and IEEE T-PAMI.